Open navigation menu

Switchboard for Voice AI
Open source tools and examples for voice AI developers.
Built to address real-world constraints
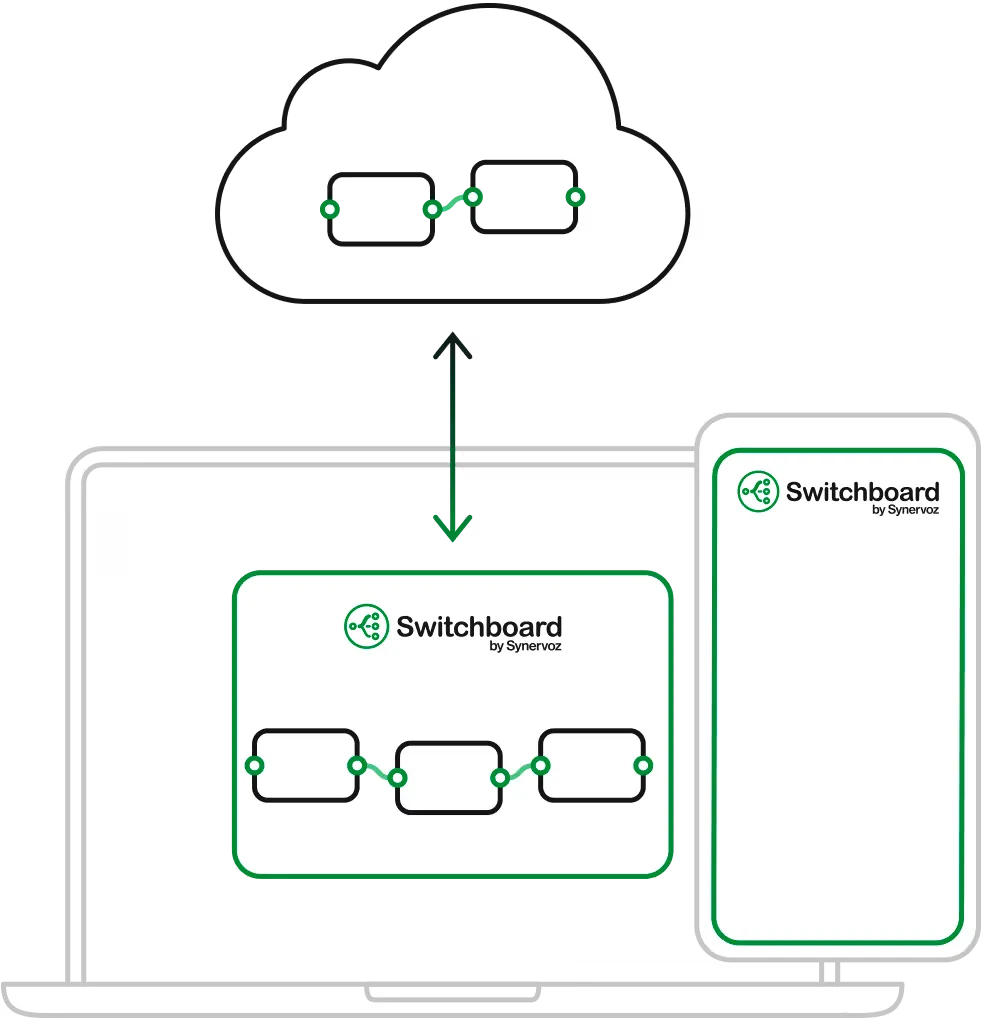
Switchboard for Voice AI uses a hybrid on-device + cloud architecture to help you get the best of both worlds. On-device processing with hand-off to cloud only when necessary.
Reduce costs
Process audio on-device to minimize expensive API calls and bandwidth usage.
Improve latency
Local processing eliminates network round-trips for near-instant voice interactions.
Enhance privacy
Keep sensitive audio data on-device and send only processed text to the cloud.
Enable offline
Build voice AI features that work without an internet connection.
Open source repositories
Production-ready examples and reusable components to accelerate your voice AI development
OpenAI Live Toolkit
Build with OpenAI’s new full-duplex Live API, where the model can listen and speak at the same time. Switchboard handles the mobile audio stack—including microphone and speaker I/O, echo cancellation, audio routing, session management, transcripts, and tool calls—through a simple React Native API, with optional on-device speaker isolation for noisy environments.
OpenAI Realtime Toolkit
Build with OpenAI’s turn-based Realtime API while Switchboard handles the complexity around it: WebSocket connectivity, native microphone and speaker I/O, echo cancellation, audio routing, and tool calls. Add on-device VAD, semantic turn detection, and tunable barge-in handling when you need faster, more controllable turn-taking than cloud-side detection alone.
EdgeSpeech
On device speech recognition (ASR / STT) and text-to-speech (TTS) so that you can cut costs and latency while simplifying cloud infra. You only send text to the LLM so don't have to worry about webRTC, sockets, or scaling audio in the cloud.
Build a full voice agent on iOS, running on-device with seamless cloud handoff when you need more intelligence. Switch between local and cloud models without losing conversation context, while keeping audio processing on the iPhone.
EdgeAudio
Coming soonOn-device preprocessing for speech to speech models (aka S2S or audio models). On device voice activity detection (VAD), echo cancellation, and other audio preprocessing runs locally before connecting to cloud-based speech model (such as OpenAI Realtime API) to optimize performance.
EdgeWhisper
Coming soonRun OpenAI's Whisper speech recognition (ASR) model entirely on-device for maximum privacy and offline functionality across mobile and desktop platforms (iOS, Android, mac, Windows, Linux).
EdgeAgent
Coming soonRun a full STT-LLM-TTS pipeline locally. The STT and LLM components each have optional hand-off (or fallback) to cloud alternatives.
EmbeddedVoice
Coming soonOptimized voice AI components for resource-constrained IoT and embedded systems, including smart speakers, wearables, and edge devices.
Need to launch faster or build something custom?
Our team offers expert consulting and forward-deployed engineers to help you design, build, and ship exactly what you need on your timeline.
All of the above can be made available on any platform.